Key takeaways
- Methodology transparency, not feature count, is the real differentiator between AI visibility tools in 2026. Vendors who disclose sample size, prompt sourcing, and rerun frequency produce numbers you can act on; vendors who say "proprietary algorithm" are usually hiding gaps.
- A SparkToro and Gumshoe.ai study found less than a 1-in-100 chance that ChatGPT or Google's AI returns the same brand list twice for an identical prompt, which means single-run "rank" metrics are close to meaningless.
- Petra Labs measured a 32-percentage-point swing in a brand's visibility across three OpenAI access surfaces (logged-in ChatGPT, logged-out ChatGPT, and the API) on the same day with the same prompt. A tool sampling only the API can report zero visibility for a brand that's actively recommended to real users.
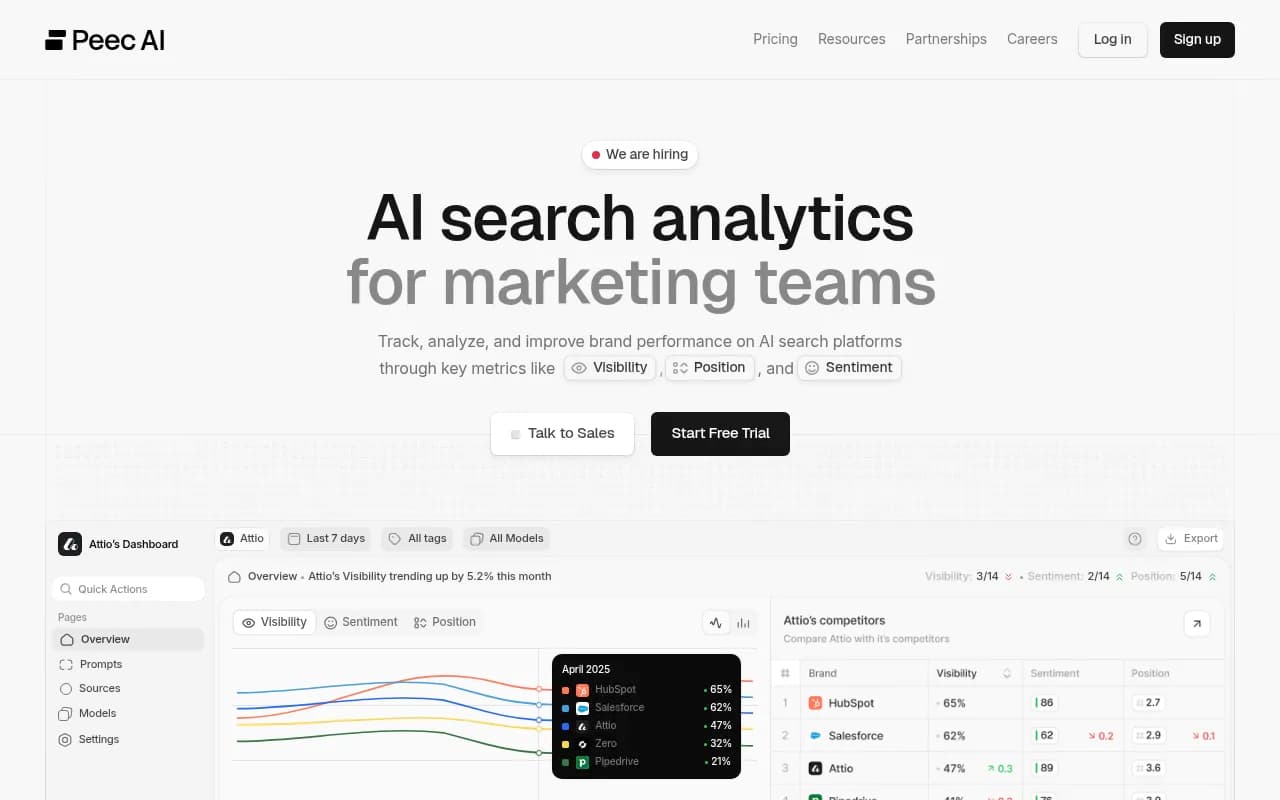
- Profound, Ahrefs Brand Radar, and Peec AI are the most forthcoming about how they build prompt sets and how often they refresh them. Platforms like Rankscale disclose simulation methods but less detail on real-user sourcing.
- Promptwatch publishes its data collection method (real UI monitoring across major AI platforms, continuously refreshed, aggregated into public reports) as a transparency benchmark worth comparing other vendors against.
Why methodology is the thing that actually matters
Every AI visibility vendor wants to sell you a dashboard with a big number on it. Visibility score: 74. Share of voice: 31%. It looks authoritative. It is not, by itself, worth anything, unless you know how that number got made.
I say this because the data backs it up in a genuinely uncomfortable way. A SparkToro and Gumshoe.ai study ran 12 prompts through ChatGPT, Claude, and Google's AI Overview/AI Mode a combined 2,961 times across 600 volunteers. The result: there's less than a 1-in-100 chance that ChatGPT or Google's AI returns the same list of brands for the exact same prompt twice. Ordering is worse, roughly 1-in-1,000 runs before two lists match in the same sequence. Response length varies too, sometimes two or three brands, sometimes ten.
That single finding should change how you read every AI visibility report you've ever been shown. If a tool ran your prompt once and told you "you rank #3," that number is close to noise. If a tool ran it 500 times across a month and told you "you appeared in 41% of responses," that's a real measurement. Same underlying event, completely different trustworthiness, and the difference is entirely about methodology.
Then there's the surface problem. Petra Labs tested the same brand, same prompt, across three different OpenAI access points: paid logged-in ChatGPT, free logged-out ChatGPT, and the raw Responses API, 300 trials per surface, 900 total, all on the same day. One brand (Renoun) appeared in 15 to 18% of chat trials and 0% of API trials. If your visibility vendor only samples the API, because it's cheaper and easier than scraping a live browser session, it will tell you your brand doesn't exist in AI answers when it actually shows up to one in six real users. Almost no vendor discloses which surface it samples from. That omission alone should disqualify a tool from serious budget conversations until it's addressed.
What a transparent methodology disclosure actually contains
Before ranking anyone, here's the checklist I used, pulled together from how the more rigorous vendors in this space describe their own process:
- Prompt sourcing: are prompts built from real search/conversation data, or invented by the vendor's team?
- Sample size and rerun frequency: how many times is each prompt run, and how often (daily, weekly, monthly)?
- Collection method: browser-based UI scraping that reflects what real users see, or API calls that can diverge from it?
- Domain/content classification: how are cited sources categorized (editorial, UGC, corporate, forum)?
- Reporting window and refresh cadence: is the question set static for months, or retested regularly as AI behavior shifts?
- Explicit caveats: does the vendor admit where its metric is modeled rather than measured?
A platform that answers all six with specifics is doing real work. A platform that answers with "our AI continuously monitors leading engines" and nothing else is marketing copy, not a methodology.
The ranking: AI visibility platforms by methodology transparency
| Rank | Platform | What it discloses | What it doesn't say much about |
|---|---|---|---|
| 1 | Profound | 1.9B+ real user prompts, 170M+ new monthly, intent/demographic breakdowns, front-end browser collection daily, published volatility research (40-60% of cited domains change monthly) | Entry pricing and full prompt caps are tier-gated |
| 2 | Ahrefs Brand Radar | Prompt set built from Google's People Also Ask corpus plus a 100B+ keyword database, two expansion systems (PAA and semantic Fanout), monthly refresh, 90-day reporting window, explicit disclosure that Share of Voice and Estimated Impressions are "modeled, not measured" | Doesn't publish raw citation logs publicly |
| 3 | Peec AI | Daily UI scraping across front-end interfaces, three core metrics (Visibility, Position, Sentiment), clickstream-based prompt prioritization | Prompt volume not broken down by intent or demographics; no Query Fanout analysis |
| 4 | Rankscale | Explicit "simulated prompts" language, 17+ engines and 240+ country/language combinations claimed, credit-based query accounting disclosed in detail | Less detail on how simulated prompts map to real user queries |
| 5 | Scrunch AI | Clear list of domains/URLs cited per tracked prompt, enterprise tier unlocks more engines and SSO | No daily rerun cadence disclosed; no published prompt-volume research |
A quick note on where this table came from: it's built from each vendor's own published methodology pages and from independent comparisons (including some written by competitors, which I've flagged where relevant since competitor-authored comparisons can be self-serving even when the underlying facts check out).
What separates the top of this list from the bottom
Profound's strongest claim is scale paired with a specific argument for why scale matters: its own research found that 40 to 60% of cited domains change monthly across answer engines, even for identical questions. That's the justification for daily reruns instead of monthly snapshots, and it's backed by a number rather than a slogan. It also explicitly argues that front-end browser responses differ from API responses, which lines up with Petra Labs' finding above, so this isn't just marketing, it's addressing a documented measurement problem.
Ahrefs Brand Radar gets credit for one thing almost nobody else does: it tells you flatly that its Share of Voice and Estimated Impressions numbers model potential visibility rather than measuring actual audience reach. That's a small sentence with a big implication. Most vendors present modeled numbers with the same confidence as measured ones. Brand Radar doesn't.
Peec AI is honest about what it is: a daily UI-scraping tool with three clean metrics and no pretense of having a giant real-conversation dataset behind it. That's a smaller claim than Profound's, but it's a claim it can actually back up, and that consistency counts for something.
Rankscale and Scrunch AI sit lower not because they're bad tools, but because they disclose less about the parts that matter most: how often prompts rerun, and how simulated queries relate to what real users type. Scrunch in particular doesn't publish anything on rerun cadence or prompt-volume research, so you're trusting the dashboard more than verifying it.
Where Promptwatch fits in this conversation
Promptwatch publishes its collection method in plain language: it pulls data from the actual user interfaces of ChatGPT, Gemini, Perplexity, Claude, AI Overviews, and other platforms, not from APIs alone, across more than 26 billion data points and growing, refreshed continuously and published as aggregated research. That real-UI emphasis matters given the Petra Labs finding that API and UI responses for the same brand on the same prompt can diverge by over 30 percentage points. Promptwatch's own published data illustrates the kind of volatility that makes rerun frequency non-negotiable: ChatGPT's average web searches per response dropped from 2.15 in early December to 1.0 by April, and average query length fell from roughly 117 characters to about 53, more than half. A tool that measured this once in December and reported it as a stable baseline would be wrong by the spring. Promptwatch's own data on source counts per response shows similar movement: Perplexity holds steady near ten sources per answer, while Microsoft Copilot has swung from under two to nearly seventeen within weeks, which is exactly the kind of instability a transparent methodology needs to account for rather than paper over.
Beyond the data publishing, Promptwatch is one of the few platforms in this category that goes past monitoring into action, with content gap analysis, automated content generation with CMS publishing, and a prioritized action list (Unified Actions) built from the same crawler and citation data it uses for measurement. That's worth knowing if you're evaluating this category for more than just a transparency score, since a platform that shows its work and then helps you fix what the data reveals is doing more than most competitors attempt.
A practical framework for vetting any vendor's claims
When a sales deck shows you a visibility score, ask these four questions before you believe it:
- How many times was this prompt run, and over what period? A single run is close to useless given the inconsistency data above.
- Was this collected from a live browser interface or an API? If the vendor can't answer, assume API, and discount the number accordingly for any brand that gets meaningfully different treatment between logged-in and logged-out states.
- Where did the prompt set come from? Real search/conversation data, or a list the vendor's team brainstormed? Brainlabs makes a good point here: visibility scores mean little if the tracked prompts barely resemble what real customers ask.
- Does the vendor admit where its numbers are modeled rather than measured? Ahrefs Brand Radar's disclosure on this is the exception, not the rule. Treat its absence as a red flag, not a neutral default.
Pricing context, because transparency and cost aren't the same axis
It's worth separating methodology rigor from price, since they don't move together. A rough snapshot from mid-2026 pricing across the category: LLM Pulse starts around $60/month, Peec AI around $80/month, Profound's entry tier around $99/month, Otterly.AI from $29/month up to $489/month at scale, and Scrunch AI's Core plan at $250/month with no free tier. Category average lands near $118/month across roughly three dozen tools compared by one third-party aggregator. None of that tells you whether the number on the dashboard is trustworthy. A $29/month tool with honest disclosures is more useful than a $250/month tool that hides its sampling method behind "proprietary algorithm."
Bottom line
If you're choosing a platform in this category, don't start with the feature list. Start by asking the vendor to explain, in writing, how many times they run each prompt, where the prompt set comes from, and whether they're reading the same interface real customers see. The platforms that answer specifically (Profound, Ahrefs Brand Radar, Peec AI, and Promptwatch among them) are the ones whose numbers you can defend to your CMO. The ones that answer with a shrug and a dashboard screenshot are selling you confidence, not data. For a broader look at the category beyond methodology alone, the GEO software directory at bestgeosoftware.com is a reasonable next stop for comparing feature sets once you've filtered for vendors willing to show their work.